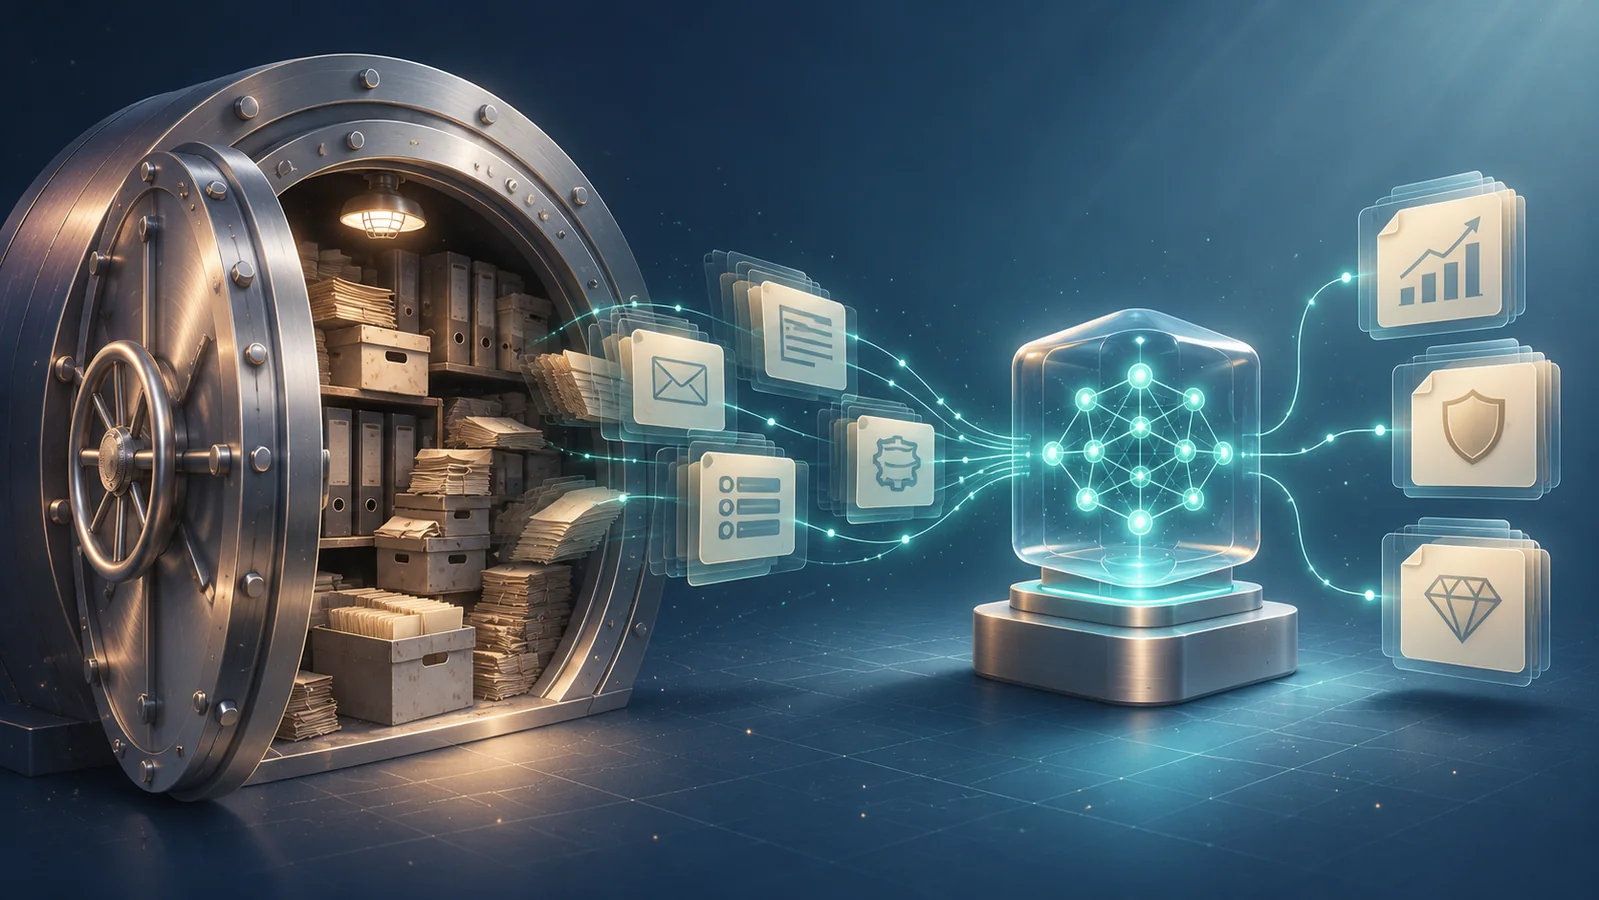
Organisations accumulate petabytes of so-called "dark data" every day: files, logs, emails or obsolete databases that evade governance processes. While these assets represent a hidden cost and a legal risk if left untapped, they also contain a wealth of information potentially exploitable by artificial intelligence. This article analyses the origins of dark data, the reasons for its proliferation, the technical mechanisms that allow AI to extract value from it, as well as the benefits, limitations and operational decisions that executives, CIOs and CISOs must make.
Introduction – A concrete problem, an emerging opportunity
The legal department of a major French bank recently discovered that millions of emails archived since 2010 had never been subject to the retention policy mandated by GDPR. The cost of their storage was estimated at several hundred thousand euros per year, with no apparent added value. Simultaneously, the data science team proposed using a Natural Language Processing (NLP) model to extract hidden fraud indicators from these same emails. The dilemma: should they invest in compliance or exploit this 'dark data' for the benefit of the company?
This example shows that dark data can be both a cost and a legal risk, but may also contain useful information. AI-Ops (MLOps) platforms and automated data catalogues now make it possible to 'de-darkify' these archives. Their use still depends on technical, organisational and regulatory conditions.
1. Dark data: precise definition and scope
| Term | Definition (source) |
|---|---|
| Dark data | 'Data assets that organisations collect, process and store during regular business activities, but generally fail to use for other purposes.' – Gartner, Data & Analytics Innovation Survey, 2022. |
| Ungoverned archives | Stored data (e.g. files, logs, databases) for which the retention policy, ownership, and compliance requirements are no longer clearly identified. |
Dark data encompasses several categories:
- System & network logs – often retained for years to meet legal or audit requirements, but rarely analysed in depth.
- Office documents – reports, studies, and presentations that remain in file shares without descriptive metadata.
- Emails and instant messaging – massive volumes, difficult to index, yet rich in business context.
- Obsolete databases – legacy systems with poorly understood schemas.
On average, according to the IDC study 'The Hidden Cost of Dark Data' (2021), 40% of organisations estimate that more than a third of their data falls into this category, with an average storage cost of US$ 6,000 per unexploited terabyte.
2. Why is dark data exploding today?
2.1 Explosion of volumes and diversification of sources
The massive shift to hybrid cloud, the rise of IoT, and the proliferation of SaaS tools have multiplied data generation points. Each micro-service or container generates its own logs; each collaborative tool creates artefacts (documents, comments). Without a centralised metadata catalogue, these flows quickly become fragmented.
2.2 Insufficient governance
Many IT departments struggle to apply Data Governance principles: appointing a Data Owner, defining a retention policy, and implementing data lineage. The lack of visibility often stems from a siloed culture where each department manages its own repositories.
2.3 Increased regulatory pressure
GDPR (Art. 5) mandates storage limitation, but compliance auditing relies on prior knowledge of the stored content. ANSSI (2023) reminds us that unmanaged archives constitute an exposure surface for compromises.
2.4 Growing maturity of AI techniques
NLP models, computer vision, and time-series analysis are now capable of ingesting raw data (free text, images, logs) with little or no human pre-processing. Transformer frameworks (BERT, GPT-4) enable named entity extraction, thematic classification, and even the detection of anomalous patterns within heterogeneous datasets.
These factors create a vicious circle: the more organisations accumulate dark data, the more they are incentivised to invest in AI to extract value from it; however, without adequate governance, the exploitation process can exacerbate risks.
3. Governance challenges and loss of control
3.1 Compliance risks
- Violation of the data minimisation principle (GDPR): retaining data that is no longer necessary exposes organisations to fines of up to 4% of their total global annual turnover.
- Right to be forgotten obligations: selective deletion is difficult when the exact location of archives is unknown.
3.2 Security risks
Dark data is often stored in unencrypted environments with weak access controls. According to the ENISA report 'Data Breaches in 2022', 27% of incidents stem from unprotected archived files.
3.3 Operational costs
- Storage (cloud, on-prem) – usage-based billing.
- Lifecycle management – additional administrative overhead.
- Degradation of search system performance when indexing unnecessary volumes.
The first step before any AI exploitation is therefore to reintegrate dark data into the governance framework: identification, classification, owner attribution, and the definition of retention policies.
4. AI as a lever for exploiting dark data – technical principles
4.1 'Data Lake + AI Engine' Architecture
+-------------------+      +-------------------+      +--------------------+
| Sources multiples | ---> | Data Lake (raw)   | ---> | IA/ML Pipeline     |
| (files, logs, DB) |      | (S3, ADLS, GCS)   |      | (Spark, TensorFlow)|
+-------------------+      +-------------------+      +--------------------+
          ^                         ^                        ^
          |                         |                        |
   Ingestion automatisée     Catalogage &               Modélisation
    (Kafka, Flume)           métadonnées                (NLP,
(Glue, Atlas) vision)- Ingestion: lightweight agents (Filebeat, Logstash) capture raw streams without transformation.
- Data Lake: cost-optimised object storage, preserving the native format of files.
- Metadata Catalogue: services such as AWS Glue Data Catalog or Apache Atlas enable each artefact to be enriched with tags (date, owner, sensitivity).
- AI/ML Pipeline: MLOps frameworks (Kubeflow, MLflow) orchestrate the training and deployment of models on catalogued data.
4.2 Adapted analysis techniques
| Type of dark data | Relevant AI technique | Application example |
|---|---|---|
| Text logs | NLP – BERT model fine-tuned for incident classification | Early detection of operational anomalies |
| PDF/Word documents | OCR + vision transformer (ViT) | Extraction of non-compliant contractual clauses |
| Archived images/videos | CNN / Vision Transformers | Analysis of production defects in industrial imagery |
| Time series | LSTM, Prophet | Server load forecasting based on historical metrics |
These approaches are based on the principle of self-supervised learning: models learn useful representations from unlabelled data, thereby reducing reliance on manual labelling.
4.3 AI Lifecycle Management – MLOps
- Dataset versioning (DVC) to ensure traceability.
- Drift monitoring: detecting changes in data profiles (e.g., new log formats) to update models.
- AI governance automation: integrating compliance rules into the pipeline (e.g., automatic removal of PII fields prior to training).
5. Realistic use case: leveraging network logs for anomaly detection
Context
A digital services company (SSN) manages several hybrid datacenters. Operations teams retain firewall, router, and IDS system logs for 5 years to meet legal requirements. No dashboards currently exist for daily analysis of this data.
AI Solution
- Log ingestion via Apache Kafka → raw storage in an Azure Blob Data Lake.
- Cataloguing with Azure Purview, enriched with a 'sensitive' tag for internal IP addresses.
- Automated pre-processing (format normalisation, removal of PII fields) using Spark SQL.
- Training of an anomaly detection model based on a variational auto-encoder (VAE), fed by the previous 12 months of data.
- Real-time deployment via Azure ML Endpoints; alerts forwarded to ServiceNow.
Results (3-month pilot period)
| Indicator | Pre-AI Value | Post-AI Value |
|---|---|---|
| Mean Time to Detect (MTTD) an anomaly | 48h | 2h |
| Monthly false positives | 0 (manual detection) | 12 (filtered by adaptive threshold) |
| Annual storage cost | €18k | €16.5k (automated purge of non-relevant logs > 90 days) |
This scenario demonstrates how dark data becomes an actionable information source, while simultaneously reducing stored volume through AI-driven intelligent purging.
6. Expected benefits of AI exploitation of dark data
| Domain | Concrete Benefit | Underlying Mechanism |
|---|---|---|
| Product Innovation | Discovery of hidden customer insights within support tickets (free text) | NLP for thematic clustering |
| Operational Optimisation | 15% reduction in incidents through early detection | Time-series models on logs |
| Compliance & Risk Reduction | Automated deletion of unlisted PII data | Governance rules integrated into the MLOps pipeline |
| Storage Cost Savings | Compression and selective purging following AI classification | Clustering algorithms to identify “cold buckets” |
| Intangible Asset Valuation | Monetisation of historical data (e.g., market research) | Metric extraction via vision transformer on archived reports |
These gains are, however, contingent upon the initial quality of metadata, the existence of a revised governance policy, and the mastery of the AI lifecycle (versioning, monitoring).
7. Limitations, Risks and Points of Vigilance
7.1 Data Quality and Relevance
AI models are sensitive to noisy, redundant, or obsolete data. Poorly structured archiving can lead to false insights and erroneous decision-making.
7.2 Algorithmic bias
When historical datasets reflect discriminatory practices (e.g., recruitment criteria), the AI will reproduce these biases, exposing the company to legal risks (GDPR Art. 22) and reputational damage.
7.3 Confidentiality and sovereignty
The processing of dark data containing personal information requires anonymisation in compliance with GDPR requirements and, where applicable, the Cloud Act or local data residency rules.
7.4 AI pipeline security
An insecure ingestion pipeline can become an attack surface (e.g., malicious file injection). ANSSI recommends implementing sandboxing and automated antivirus scans prior to storage in the Data Lake.
7.5 Orchestration cost
Deploying a full MLOps stack (catalogue, orchestration, monitoring) involves significant initial expenditures, which are often underestimated by decision-makers.
7.6 Legal liability of AI
In the event of a decision-making error based on an AI model (e.g., rejection of a customer request), liability may rest with the company, even if the model was trained on unmanaged internal data.
Points of vigilance
Verify data lineage traceability* prior to any training.
* Implement a human-in-the-loop validation process for high-impact cases.
* Ensure that encryption at rest and in transit covers the entire pipeline.
8. Decision guide: moving from theory to implementation
| Step | Key action | Responsible party(ies) | Deliverable |
|---|---|---|---|
| 1 – Mapping | Inventory dark data sources (logs, files, databases) | CIO / Data Owner | Inventory report with sensitivity classification |
| 2 – Governance | Define retention policy & assign Data Stewards | DPO, CISO, Management | Data lake governance charter |
| 3 – Technical Platform | Select a Data Lake (e.g. Azure Blob) + catalogue (Purview) | Cloud Architect | Target architecture (diagram) |
| 4 – AI Pilot | Choose a high-value use case (e.g. network logs) | Data Science Team | Trained model, performance metrics |
| 5 – MLOps | Implement CI/CD for models and data versioning | DevSecOps Lead | Automated pipeline (GitLab CI, MLflow) |
| 6 – Security & Compliance | Apply encryption, PII masking, and audit logging | CISO | Pipeline security audit report |
| 7 – Deployment & Monitoring | Deploy to production, monitor drift and costs | IT Operations | KPI Dashboard (detection, storage cost) |
| 8 – ROI Evaluation | Calculate savings + added value over 12 months | CFO, CIO | ROI Dashboard |
Recommended tracking indicators
- Automated classification rate (%) – proportion of files tagged by AI.
- Average storage cost per terabyte (€/Mo) – before/after intelligent purging.
- Mean time to detect anomalies (hours).
- GDPR compliance score (internal audit, 0‑100).
Operational conclusion
Dark data represents both a financial burden and a legal risk, but also a source of strategic insight when correctly governed and leveraged by artificial intelligence. The key to success lies in a gradual approach: mapping archives, establishing robust governance processes, and then deploying automated AI pipelines (MLOps) capable of analysing this raw data while respecting confidentiality and security.
Organisations that succeed in 'de-darkifying' their archived assets will gain decision-making agility and reduce costs